Hi, this is Gergely with a bonus, free issue of the Pragmatic Engineer Newsletter. In every issue, I cover Big Tech and startups through the lens of senior engineers and engineering leaders. Today, we cover one out of four topics from last week’s issue of The Pulse. Full subscribers received the article below seven days ago. If you’ve been forwarded this email, you can subscribe here.
Firebase – built by Google – has had a nasty outage this week with shockingly poor incident management at odds with how Google itself usually deals with high-severity incidents.
The outage started on Tuesday (29 Sep) at 5:41pm (PDT), when iOS apps using the Firebase SDK started to crash upon first opening; every iOS app that uses the Firebase SDK with analytics enabled was affected in this way. Developers of affected apps opened a GitHub ticket, in the absence of much else to do. On the ticket, the message “it’s crashing for me too!” was oft-repeated.
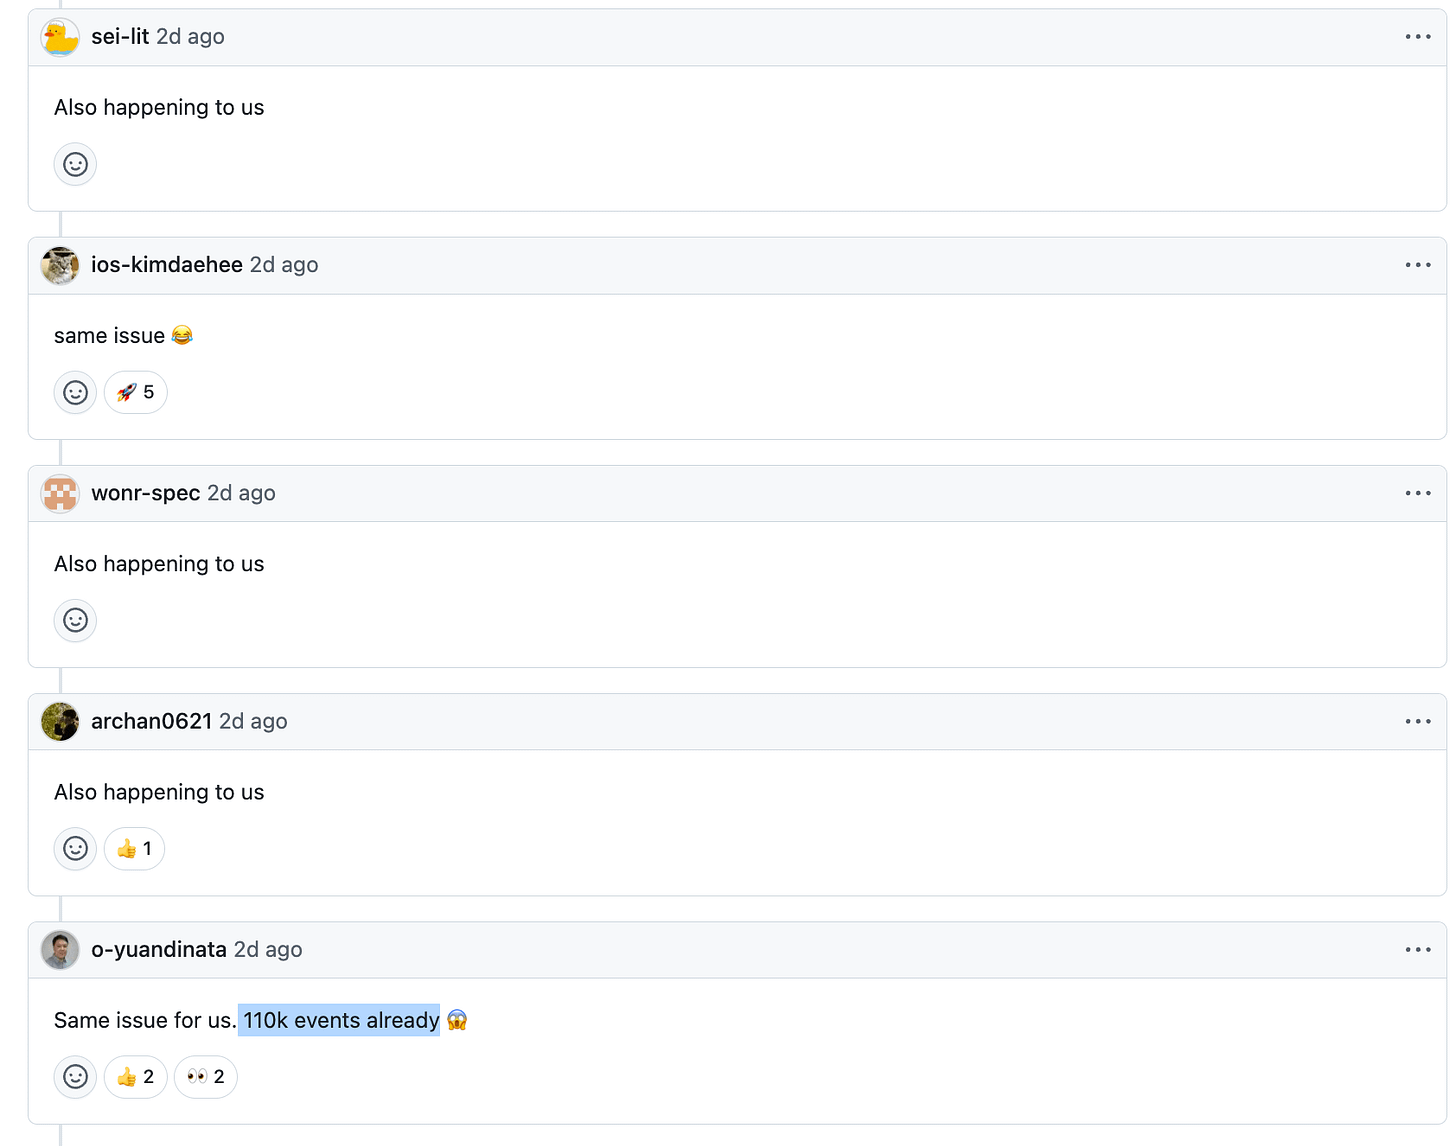
6:51pm (PDT): acknowledgement. An hour and ten minutes after the crashes started, an engineer on the Firebase team acknowledged that they were aware of the outage.
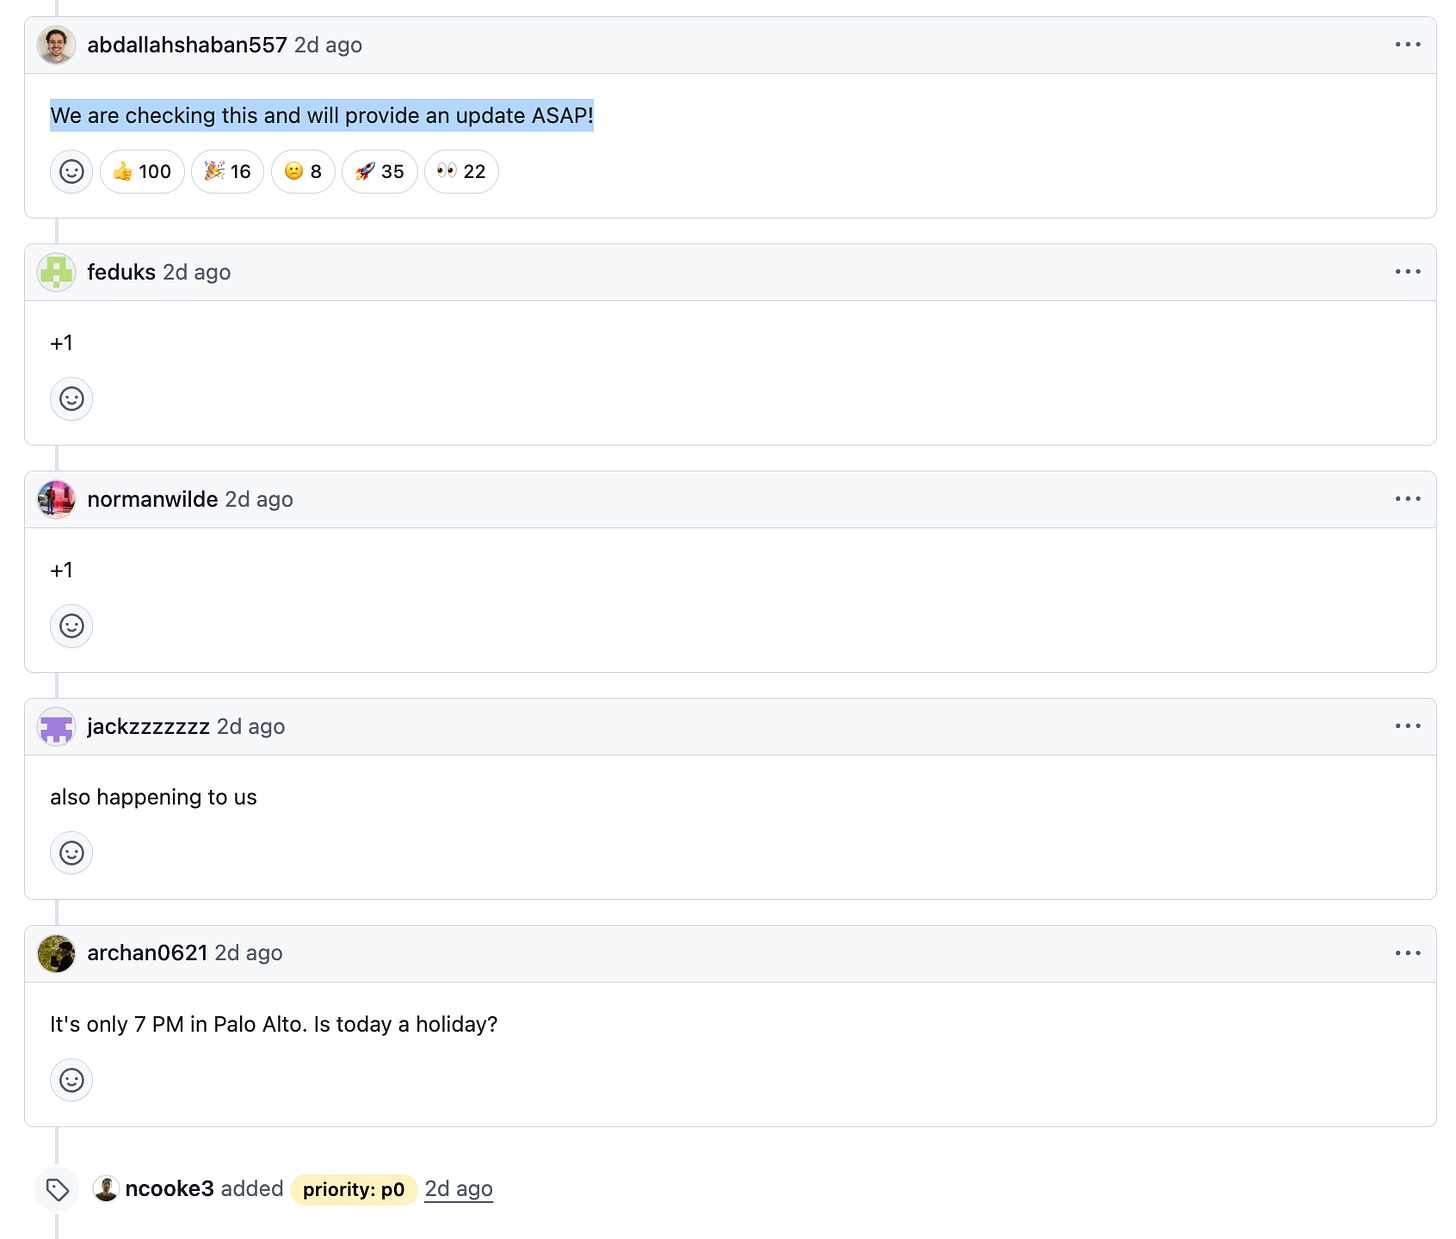
It’s unclear if the Firebase team was alerted via this ticket with 100+ comments by devs, or if Google’s own monitoring tool showed the issue. I asked Google/Firebase two days ago and haven’t had a response.
Not having anything better to do than wait for Google to resolve the issue, the memes began:
Others attempted to help the Firebase team by pinpointing the potential issue. Indeed, before a Google engineer acknowledged the incident, an external developer found the root cause at 6:37pm PDT; it was a zero-length entry that was crashing the SDK:
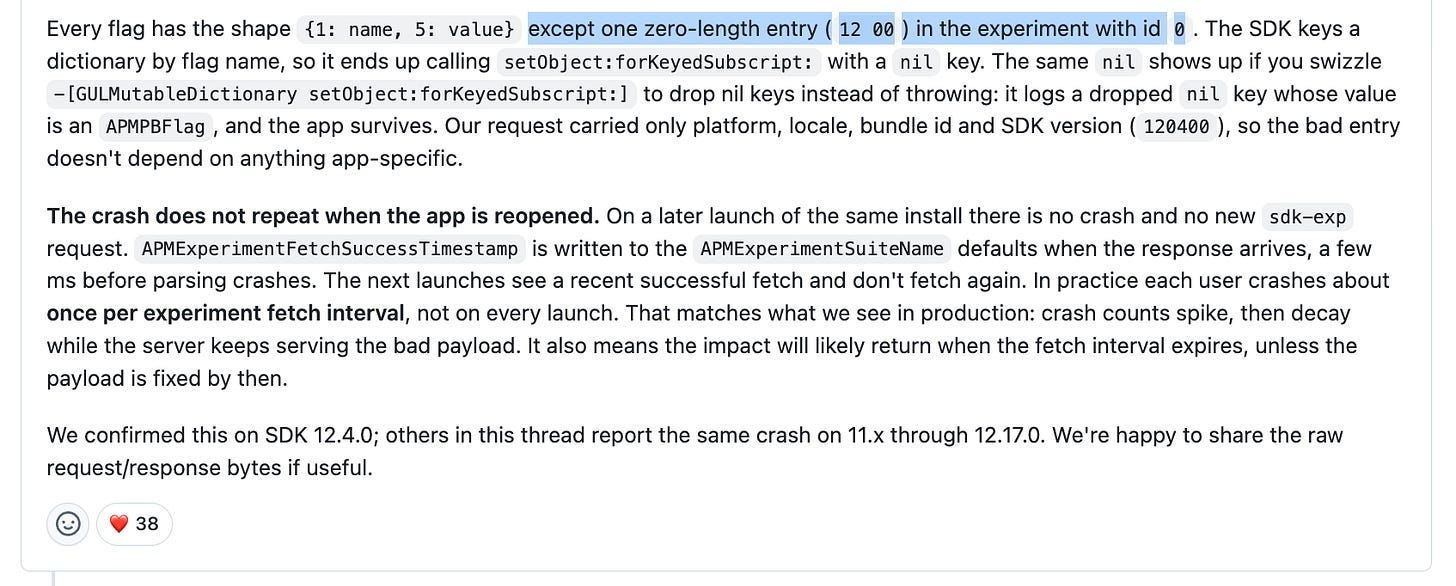
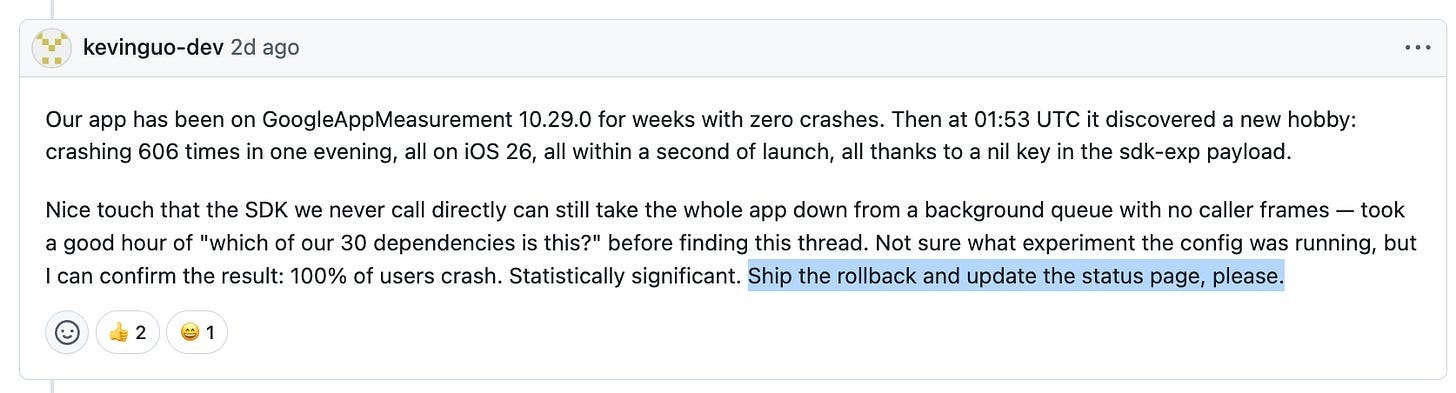
Given the flags are shipped by the backend, the offending change was a backend one, and the easiest resolution would be to roll it back, which the community practically begged Google to do:
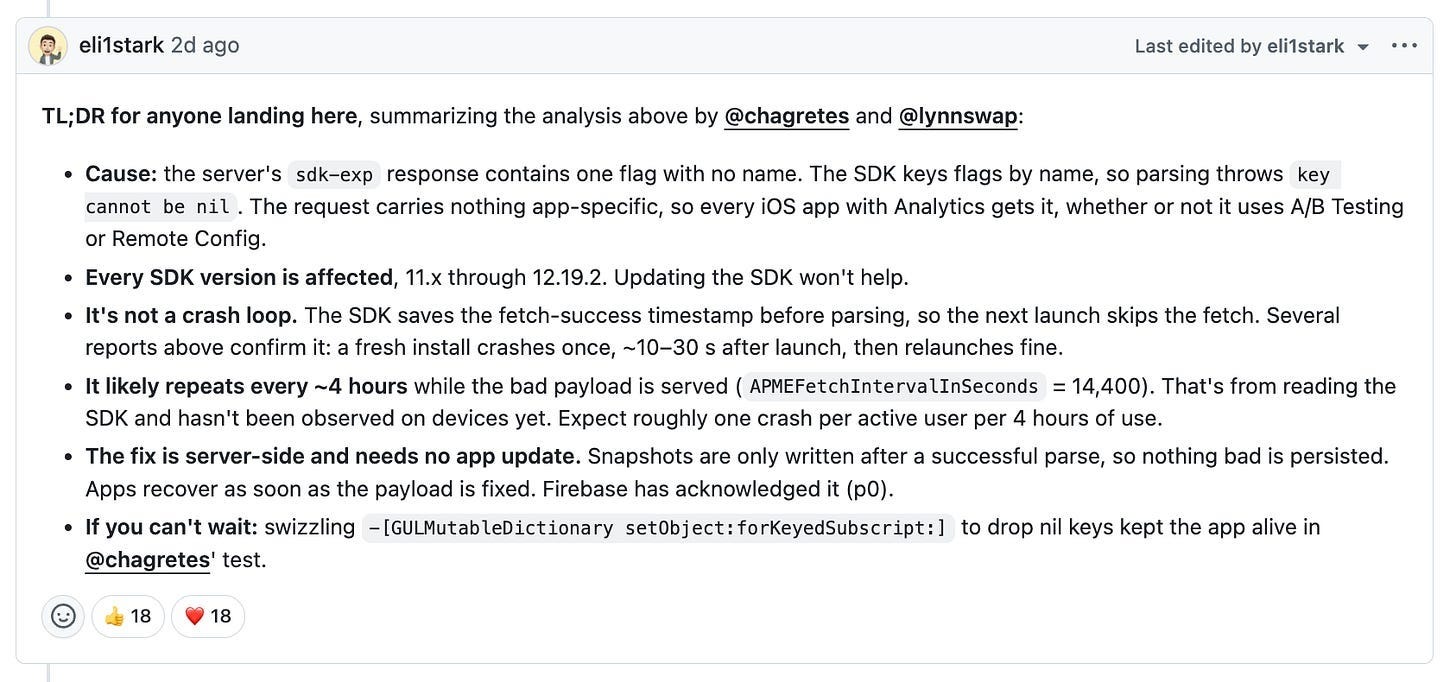
Here’s a neat summary of the incident from another dev:
7:24pm (PDT): rollback starting. An hour-and-a-half into the incident, the Firebase team started rolling back the offending backend change:
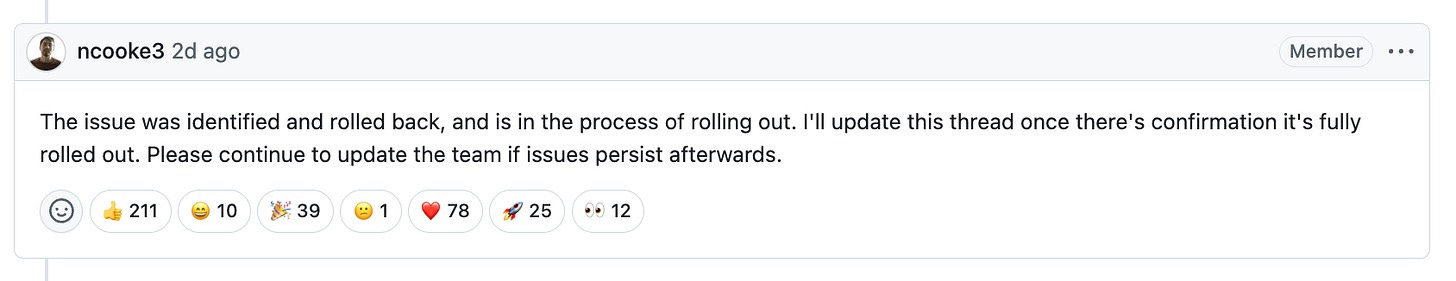
8:16pm (PDT): rollback complete. And the rollback completed ~50 minutes later:
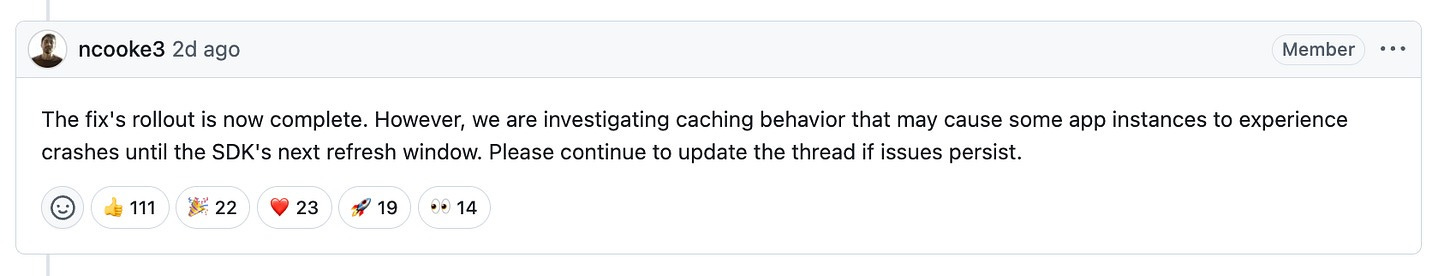
Software engineer, Nick Cooke, on the Firebase team posted a summary with more accurate timestamps:
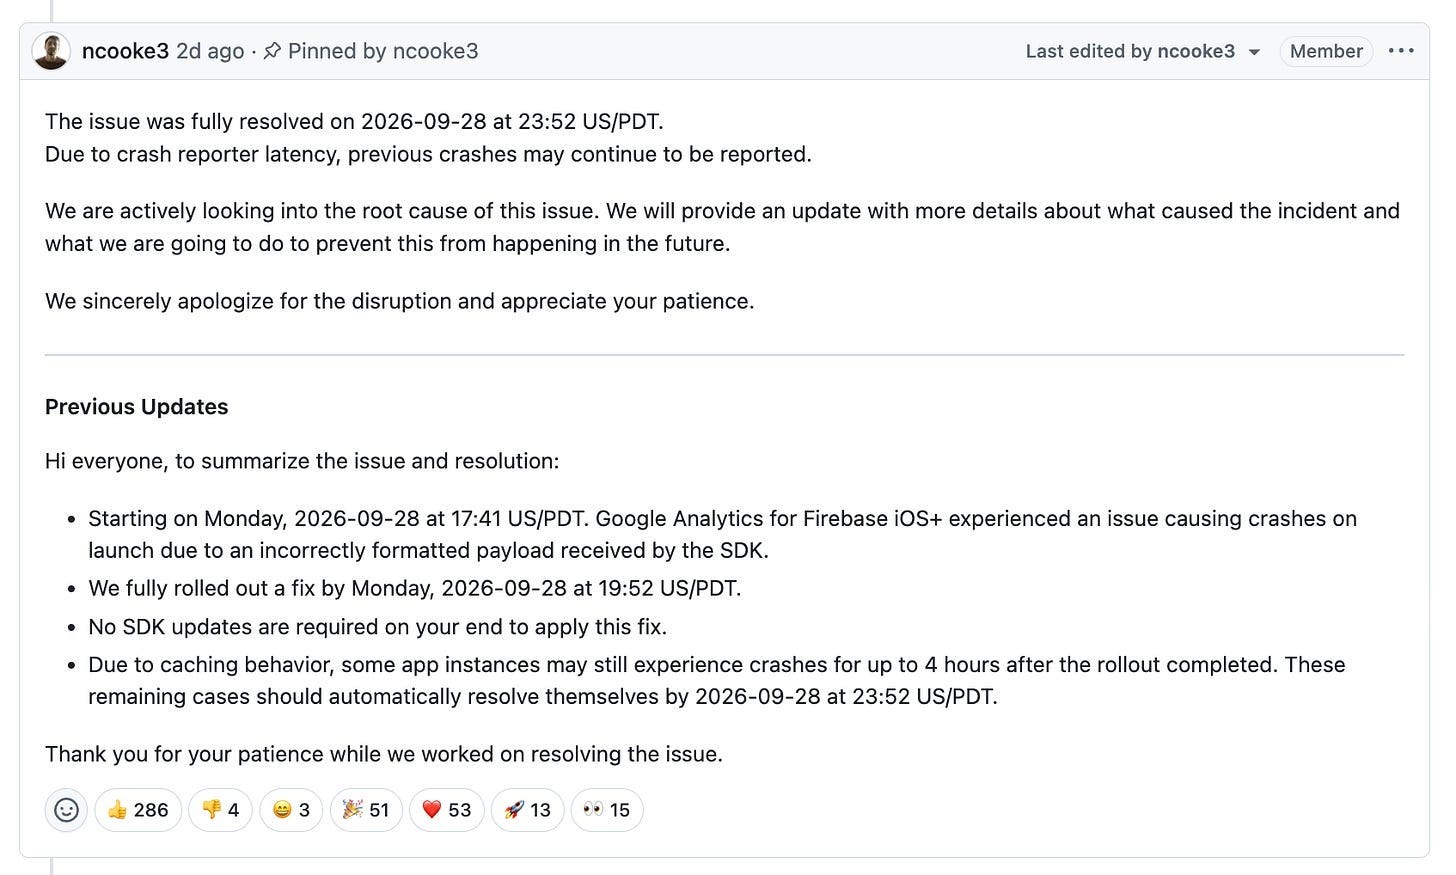
What we can deduce from this:
- TTD (time to detect): one hour? The Firebase team never shared how long it took them to detect that practically all iOS apps using Firebase had started to crash. On the GitHub ticket, they acknowledged the incident 70 minutes after it started. Update: in the postmortem, later published by the team, they wrote how the team was alerted 20 minutes after the rollout, via crash alerts and GitHub issues. Good question why it took another 50 minutes to acknowledge the issue, though?.
- TTM (time to mitigate): 2-6 hours. It took two hours and eleven minutes to roll out the fix, but due to caching (apps that had cached the incorrect server response served this cache for additional four hours, and so kept crashing for up to six hours.)
Incident management basics
The Firebase team itself closed the outage with a short report effectively saying that there had been an outage, but they’d resolved it now, so thanks for your patience and have a nice day.
This handling of a high-impact incident is absolutely not typical of Google, the company that coined the term ‘Site Reliability Engineer’ and wrote the SRE book.
For one, Firebase never bothered updating its status page. Oddly enough, the official Firebase status page showed all systems green – despite the acknowledgement of the outage. Indeed, during it and afterward, they didn’t update the status page to indicate the lengthy outage:
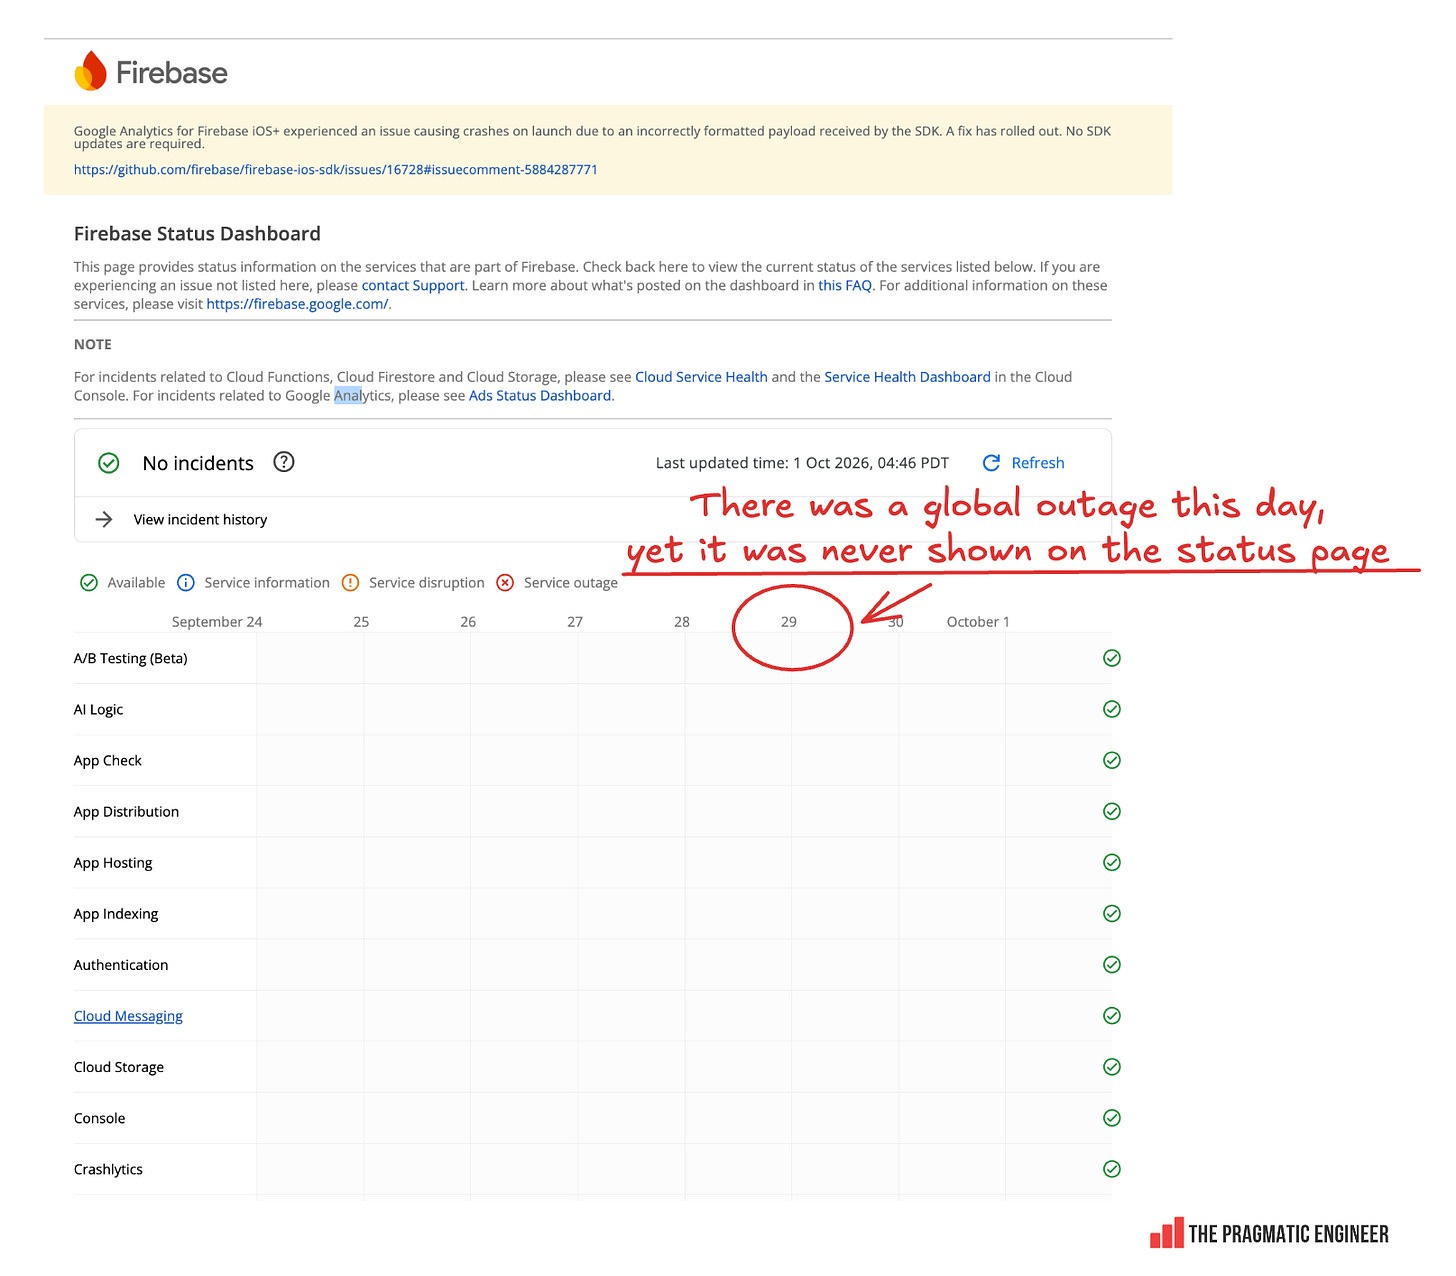
But status pages exist for good reasons, including:
- To communicate with customers during and after an outage
- Offer transparency on the stability of the service
It’s worth asking: if an outage that takes down most (or all?) iOS apps using Firebase doesn’t warrant an update to the status page, then what does!
Google published a postmortem four days later, answering questions on how the outage happened. On Friday, 2 October, Google published a postmortem on the Firebase blog. It was a configuration change that crashed so many iOS apps. From the postmortem:
“On September 28, 2026, a routine configuration cleanup unexpectedly caused a large number of iOS applications using the Google Analytics for Firebase (GA4F) SDK to crash.
2026‑09‑28 17:38 (PST): A stale, legacy configuration flag was cleaned up.
2026‑09‑28 17:41 (PST): The malformed configuration payload begins rolling out globally to production servers. Outage begins: Clients fetching the new payload start crashing on launch.
The SDK missed validating that a flag’s name was not nil, ultimately causing the crash. Backend data anomalies should not cause app-side crashes.”
In the postmortem, Google noted that engineers were alerted to the outage through both GitHub reports coming from external developers, as well as their internal monitoring. It took another hour to pinpoint the cause being a legacy configuration flag cleanup.
Firebase says they have no way to update their status page for client-side outages. In the postmortem, Google explained that there is no place to indicate client-side outages on their dashboard (emphasis mine):
“Throughout the outage, both the Firebase and Google Ads status dashboards remained green. Because these dashboards rely primarily on server-side health metrics, they did not register client-side SDK crashes.
Commitment: Moving forward, we are actively working to: integrate SDK-related outage information into our status dashboards, streamline the manual update process, and improve GA4F status representation within the Firebase dashboard.”
It’s good to see Google not dropping the ball fully, and recognizing that both their dashboards and their incident management process need improvement.
It’s fair to ask though: why did only iOS crash, and not Android? Firebase’s Android SDK seems to be hardened more than iOS, as the feature flag removal did not crash Android devices.
Especially that now, with AI, it’s easier than ever to compare iOS and Android implementations to ensure they are identical – and it’s what Shopify has been doing during their native rewrite – could it have been a missed opportunity for Google to audit the differences between the iOS and Android SDKs? To me, not having an action item here feels like a missed opportunity.
Still, this is a good reminder to anyone and everyone shipping iOS and Android apps: aim to harden them, and when possible, run tests with malformed payloads, then fix crashes those payloads cause.
Déjà vu: the 2020 Facebook SDK crash
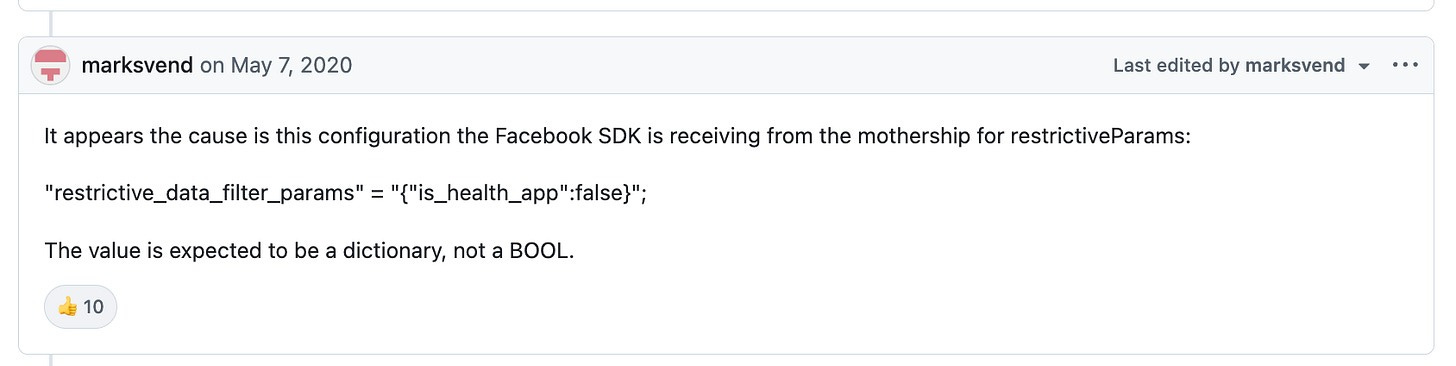
The last time there was a similar crash was in 2020, with Facebook. That May, apps such as Spotify, TikTok, Pinterest, and others also started to suddenly crash due to the Facebook SDK crashing all apps using it. Back then too, devs followed along on a GitHub ticket and they also found that bug: a value that should have been a dictionary but was a boolean:
Then as now, there was banter by devs being made to wait for a fix:
And requests to not move fast and break things any more:
Making light of the situation:
And also anticipating the resolution:
In the end, Facebook reverted the backend change, but shared even less than the bare minimum details from Google this time. This is all we know about that 2020 outage that was arguably more wide-ranging than the Firebase one:
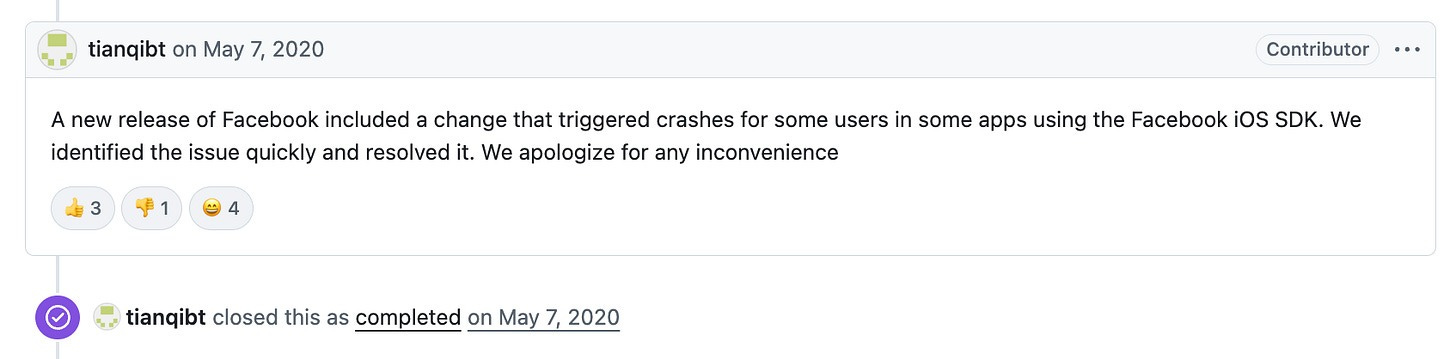
I wonder if some people think that public-facing incident management is no longer important or valuable, even for developer-facing products. I’m not shocked that Facebook/Meta never bothered to communicate much about their outage because dev tools are not part of the DNA there.
But with Firebase, I am surprised that more than a week later, the postmortem is still not visible on the Firebase status page.
And maybe this is Google “shipping their org chart” playing out, live. The outage technically was caused by Google Analytics (who made the feature flag change), but is the responsibility of the Firebase SDK (whose iOS SDK was not hardened enough to deal with this new payload). The outage itself was buried inside a Google Ads dashboard (!!) which suggests that whatever team is seen responsible for the outage is inside the Google Ads organization.
In the end, despite the Firebase team committing to “improving status dashboard latency and coverage,” last week, those teams are in no hurry to carry out this work. AI agents might be making lots of work more efficient, but following up on action items seems to move at the same snail pace at Google, as it did pre-AI!
Read the full issue of The Pulse this is from, or check out this week’s The Pulse. This week’s issue covers:
- New trend: building internal vibe-coding platforms at mid-sized companies. Ramp and Stripe built platforms for non-engineers to build internal websites and tools with, and both are taking off in those workplaces. I expect more companies to do the same.
- Do us engineers really enjoy hard problems? Or do we actually like pattern-matching with backend problems? A provocative post by Cloudflare engineer, Sunil Pai, suggests there are other motives.
- New open models launch in the EU and US. Kolibri, Mistral Large 4, and Beam by Reflection could challenge China’s dominance in open weight models.
- Industry Pulse. Why Figma doesn’t let any agent use its MCP server; Google Cloud adds Swift support on the server side, Anthropic’s two-week sprint to speed up Claude Code, Coinbase dumps React Native shortly after Shopify announces doing so, Claude Opus 5.5 formats the C: drive, and more.
Subscribe to my weekly newsletter to get articles like this in your inbox. It's a pretty good read - and the #1 software engineering newsletter on Substack.